
What Consistent Profits Mean in Forex
For this article, consistency means that a defined trading process produces results that remain reasonably stable when the same rules are tested across instruments, periods, and cost assumptions. It is not established by one profitable month, one pair, or one performance metric.
Three questions matter:
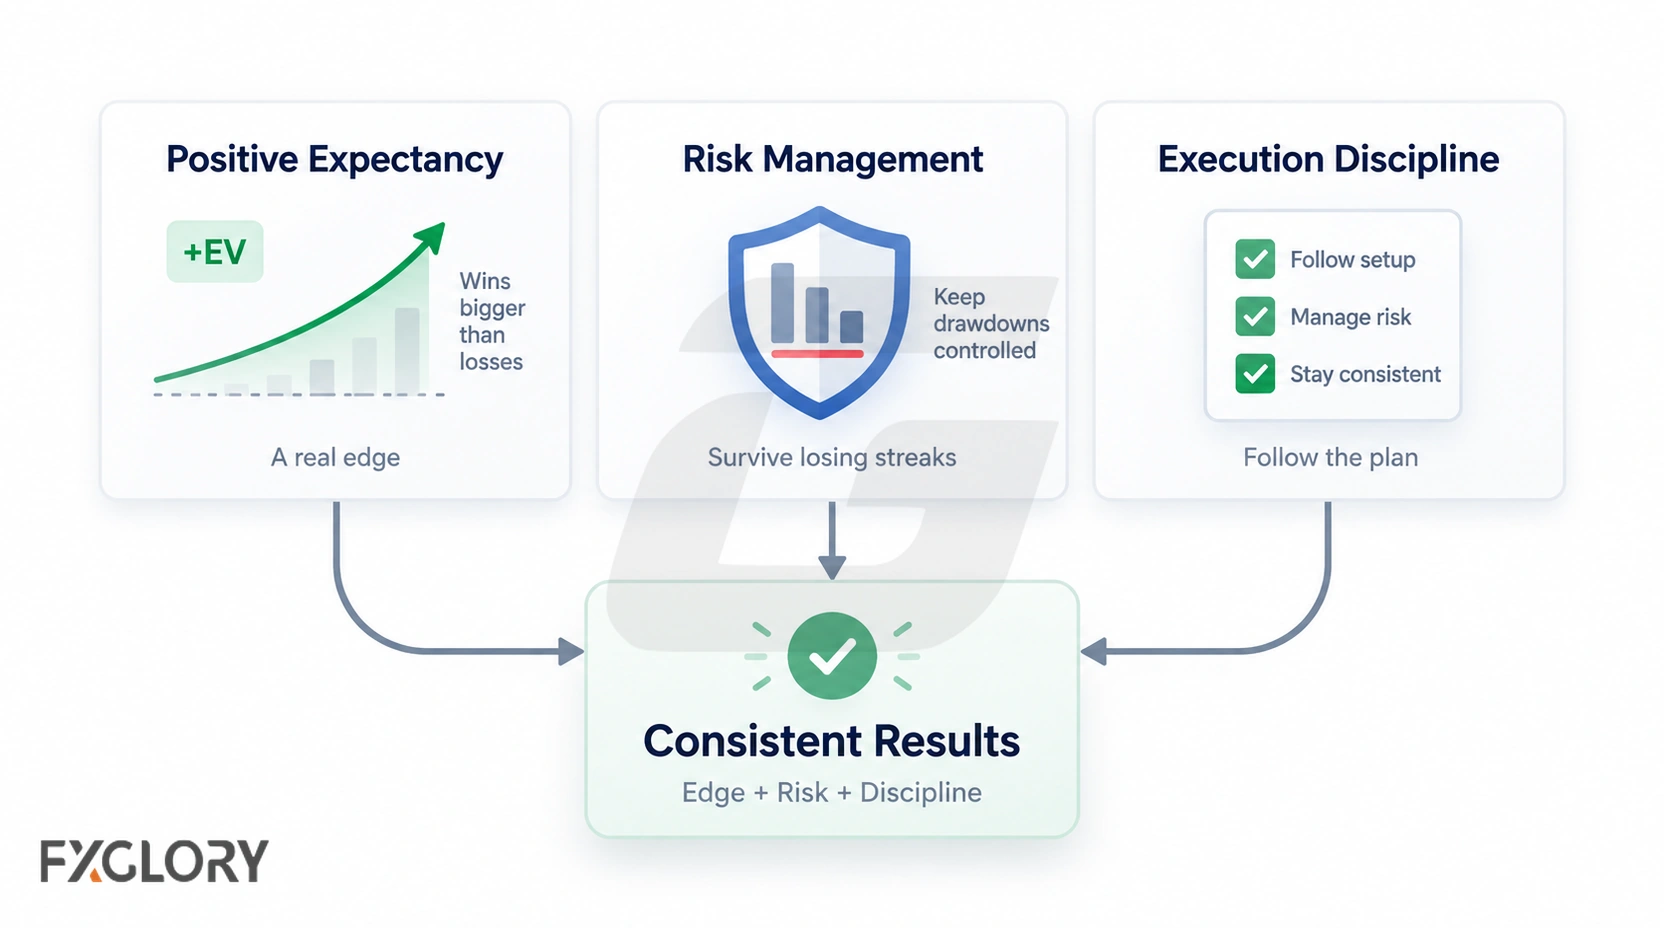
- Does the tested rule model have positive expectancy after relevant costs? Expectancy combines win rate, average win, and average loss.
- Can the observed drawdowns and losing streaks be tolerated within the chosen risk model? Backtest drawdown describes the tested sample, not a guaranteed future limit.
- Can the rules be executed as written? If entries, exits, or position sizing change from trade to trade, the resulting performance no longer represents the tested model.
No universal number of trades makes a strategy statistically significant. Larger samples generally reduce uncertainty, but the required sample depends on trade frequency, variance, independence, the metric being estimated, and the statistical method used.
Why Win Rate Does Not Measure Consistency
Win rate is easy to understand, but it does not show how much the average winning trade earns, how much the average losing trade loses, or how trading costs affect the result.
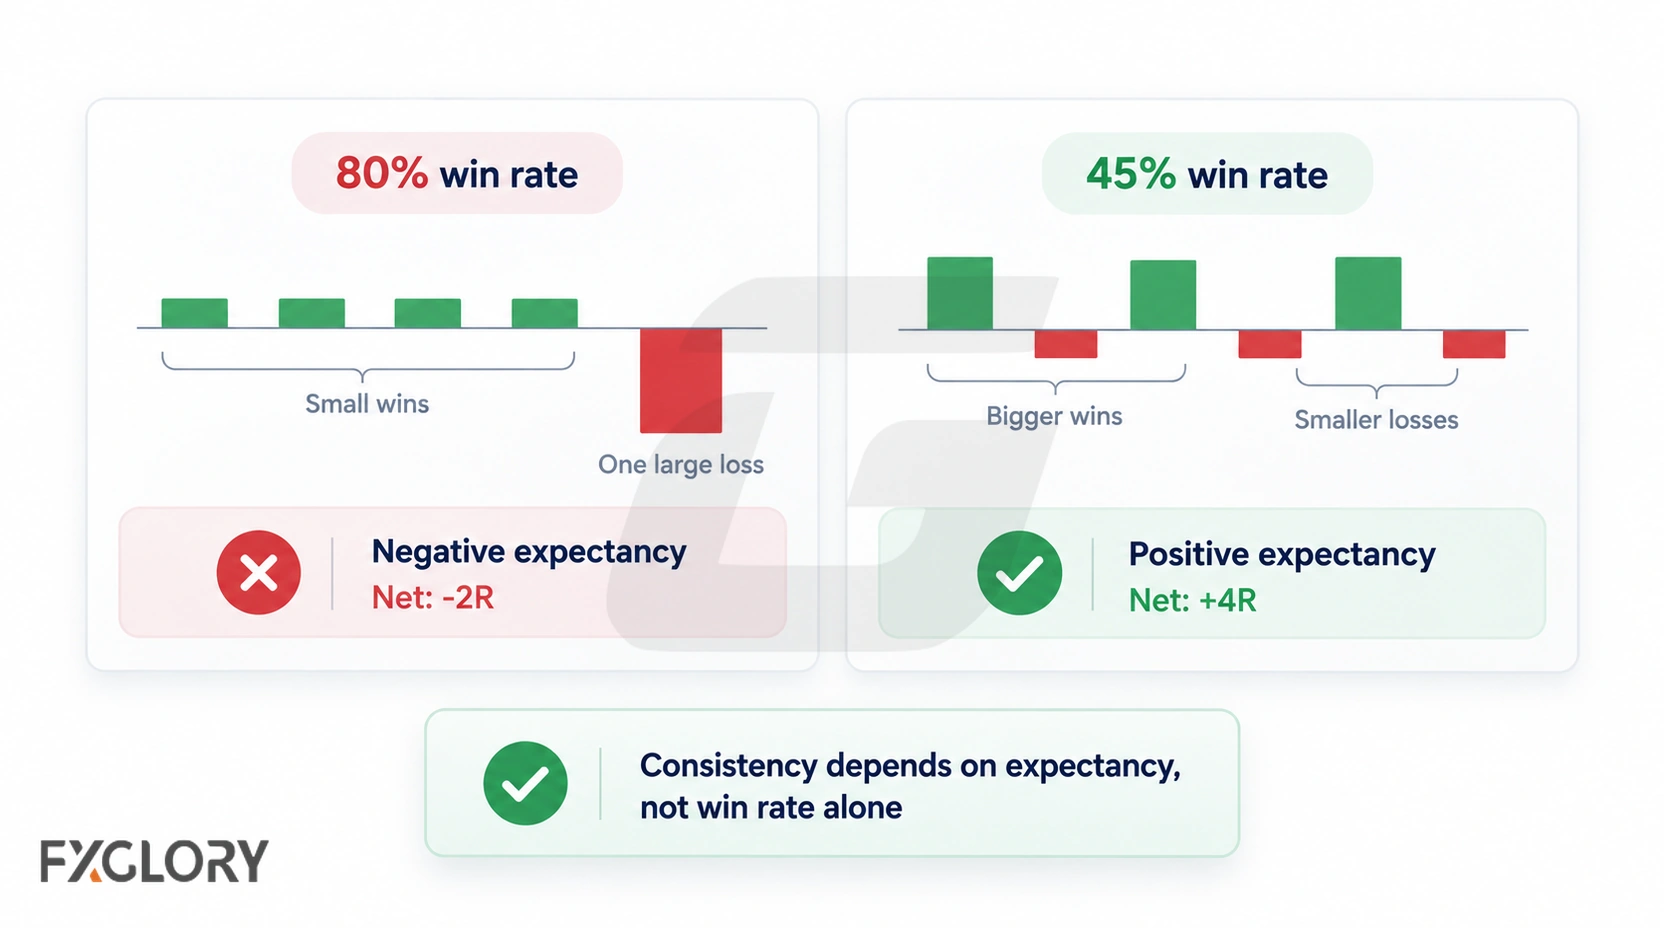
The relationship can be summarized with expectancy:
Expectancy = (Win Rate × Average Win) − (Loss Rate × Average Loss)
A rule model can therefore win less often and still outperform a higher-win-rate model if its average winning outcome is sufficiently larger relative to its average loss.
| Win Rate | Average Win | Average Loss | Expectancy Per Trade |
|---|---|---|---|
| 70% | 20 pips | 50 pips | -1 pip |
| 50% | 30 pips | 30 pips | 0 pips before costs |
| 40% | 50 pips | 30 pips | +2 pips before costs |
| 35% | 80 pips | 30 pips | +8.5 pips before costs |
| 25% | 120 pips | 30 pips | +7.5 pips before costs |
The study below provides a concrete example: Strategy B had the highest combined win rate, but its combined expectancy remained negative. The detailed figures are shown once in the results section rather than repeated throughout the article.
Three Components to Evaluate Together
Component 1: Positive Expectancy
A strategy needs rules that are specific enough to test. Entry, invalidation, exit, and position-size logic should be defined before results are evaluated.
Expectancy = (Win Rate × Average Win) − (Loss Rate × Average Loss)
Positive expectancy in a historical sample is evidence about that sample, not proof of a permanent edge. It should be checked across pairs, periods, parameter choices, and realistic costs.
Component 2: Risk and Drawdown
Losing streaks are normal in any probabilistic trading process. Risk management should be based on the size and variability of losses that the strategy can produce, not on a fixed percentage that is assumed to fit every system.
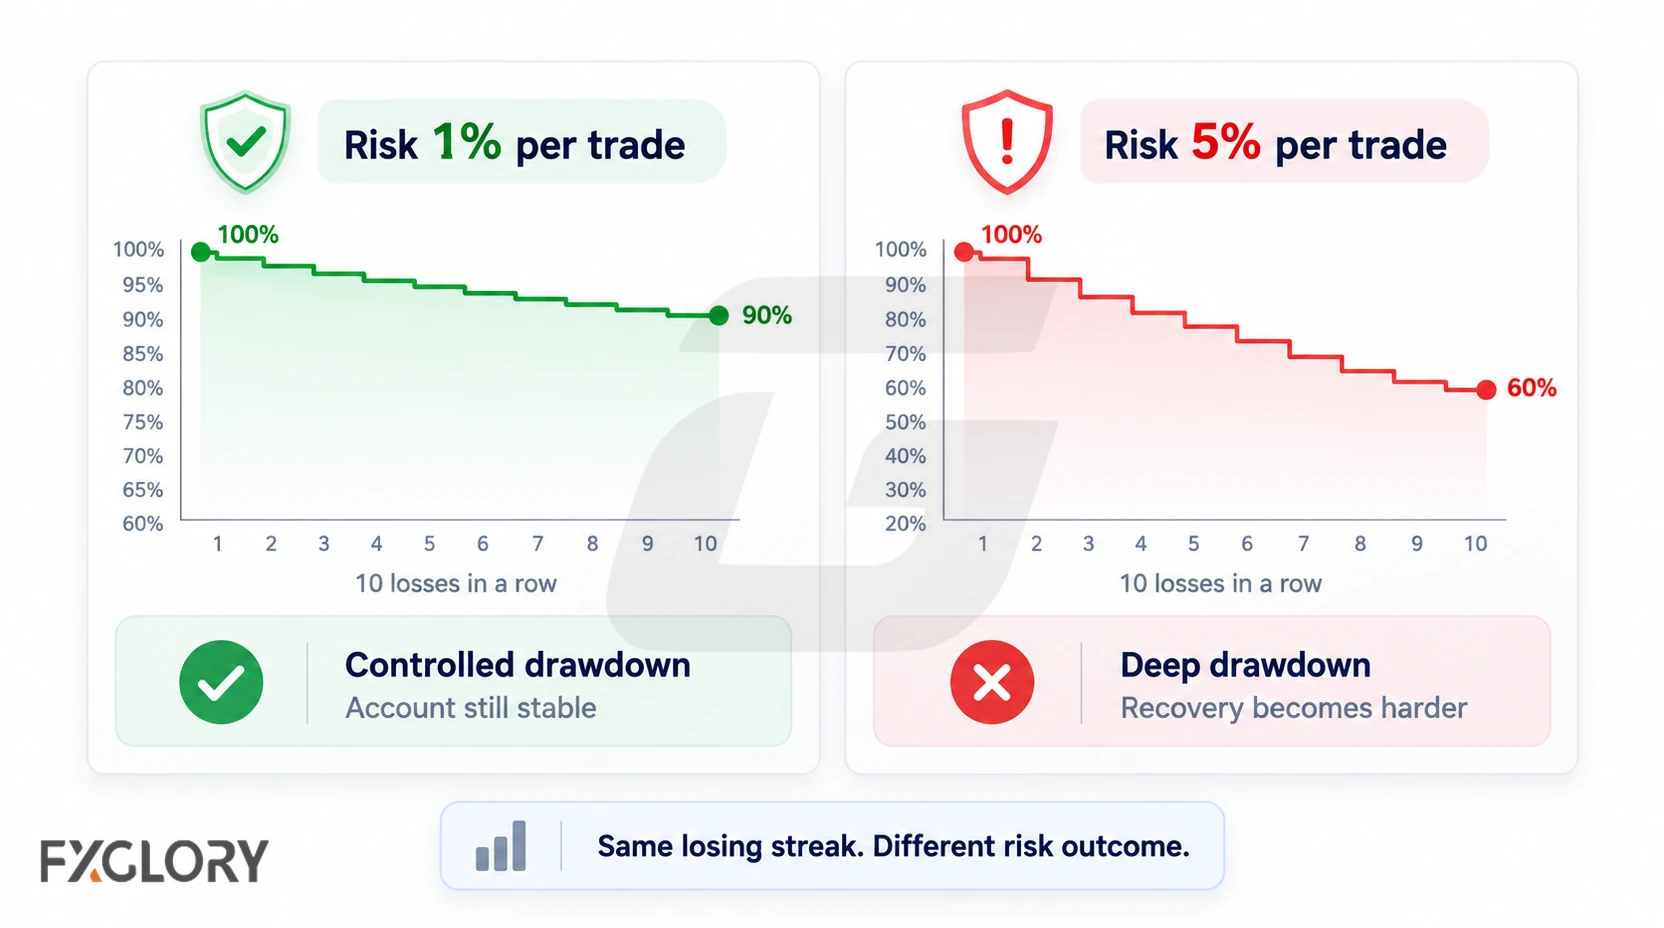
Useful controls include position sizing based on stop distance, limits on total correlated exposure, and predefined account-level risk limits. For a deeper treatment, see the forex risk management strategy.
Component 3: Rule Adherence
A backtest describes a specific set of rules. If a trader skips valid signals, takes invalid ones, changes stops, or changes size after losses, live results no longer represent the tested process.
Disciplined execution does not guarantee better performance than another trader. Its value is that it makes the process measurable: differences between the tested model and actual execution can be identified and reviewed.
How to Measure Whether a Strategy Is Consistent
| Metric | What It Measures | How to Interpret It |
|---|---|---|
| Profit factor | Gross profit ÷ gross loss | Above 1.0 means gross profit exceeded gross loss in the tested sample; below 1.0 means gross loss exceeded gross profit. Interpret the magnitude with trade count, costs, drawdown, and out-of-sample behavior. |
| Expectancy | Average outcome per trade | Review the overall value and how it changes by pair, period, and cost assumption. |
| Maximum drawdown | Peak-to-trough decline in the tested sequence | Use it as a historical stress measure. It is not a guaranteed future maximum. |
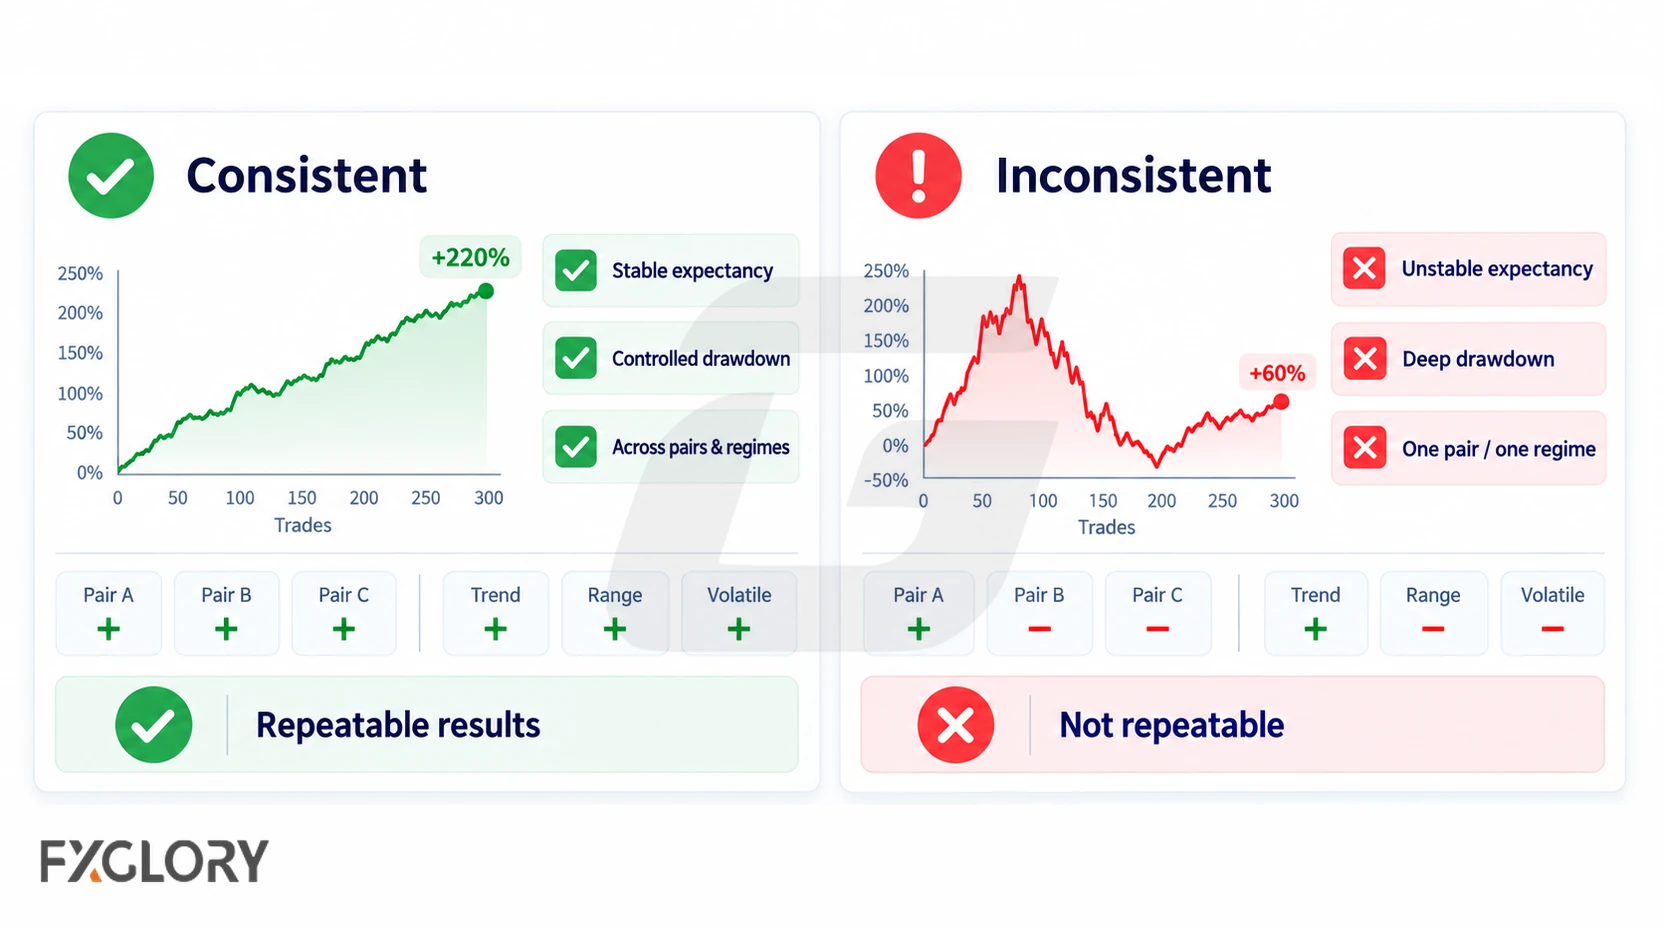
| Cross-pair variation | How results differ across instruments | Large differences can indicate that the rule model is pair-sensitive rather than broadly stable. |
| Equity-curve behavior | How cumulative results evolve through the sample | Use visual inspection only as a diagnostic. Smoothness alone does not establish consistency because trade frequency, aggregation, and sampling can change the curve's appearance. |
A Practical Testing Framework
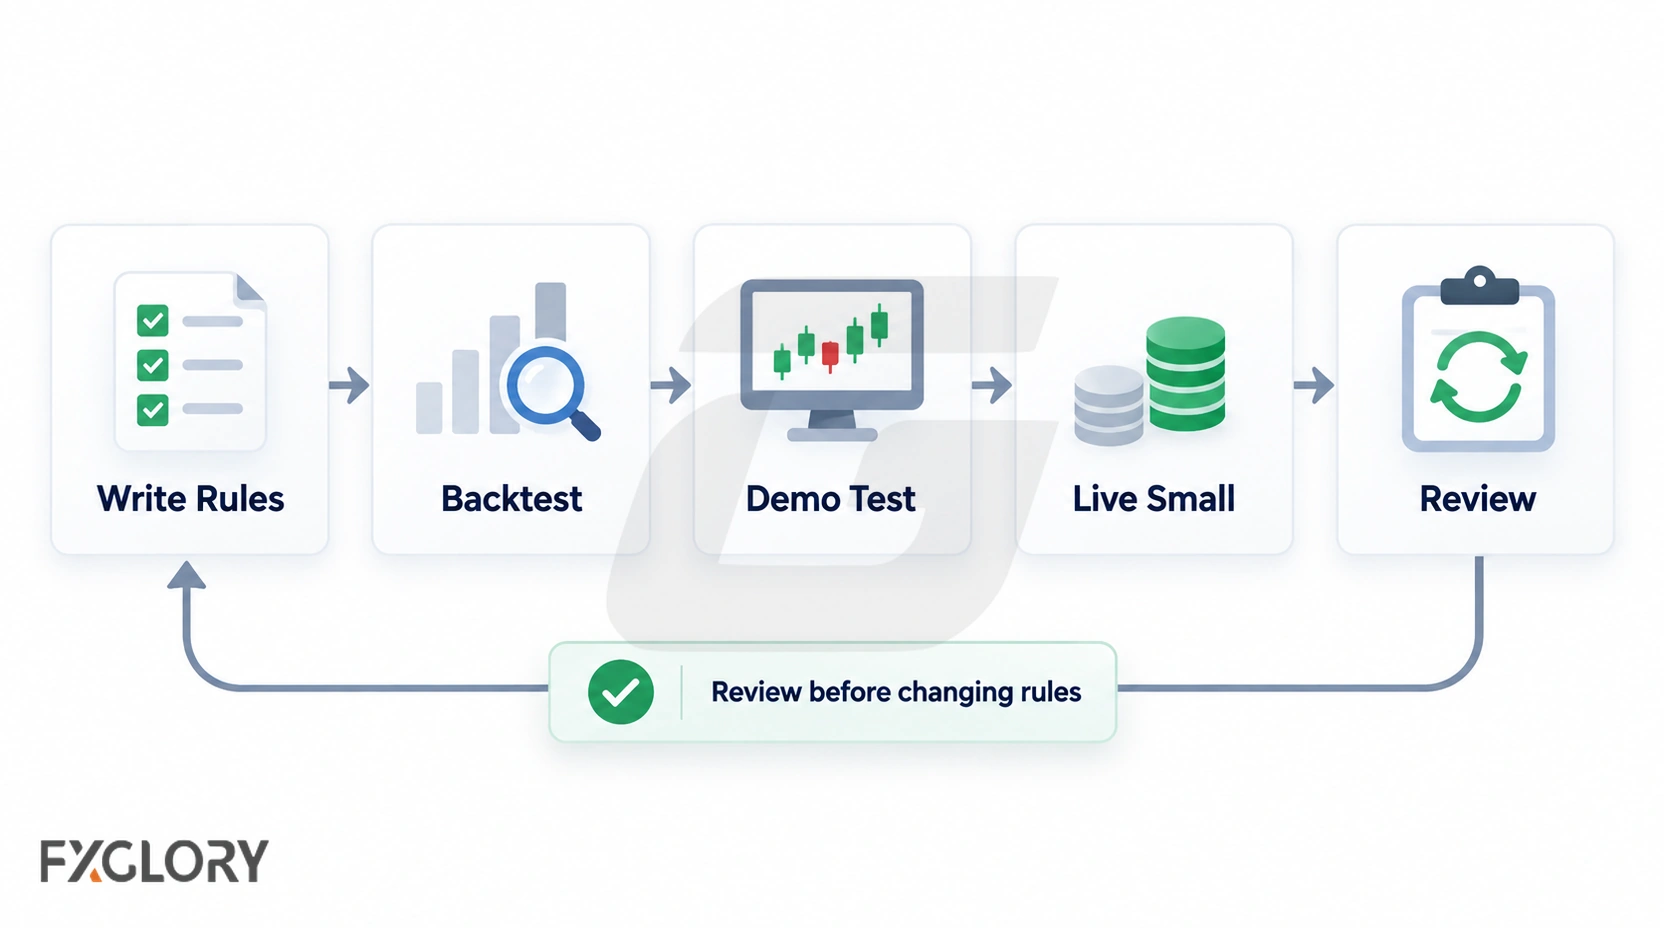
| Stage | Purpose | Main Question |
|---|---|---|
| 1. Define the rules | Write entry, invalidation, exit, sizing, and market filters. | Can another person apply the same rules without guessing? |
| 2. Backtest historical data | Measure how the rules behaved across different periods, pairs, and cost assumptions. | Is the sample large and varied enough to support the conclusions being drawn? |
| 3. Forward-test | Apply the rules to new data as it arrives, often in demo before live risk. | Do execution and cost assumptions differ from the backtest? |
| 4. Evaluate live execution cautiously | If live trading is appropriate, use position sizing that keeps losses affordable while comparing actual execution with the tested rules. | Are spreads, slippage, behavior, and fills materially changing the result? |
| 5. Review before changing parameters | Separate execution errors from model weaknesses. | Did the strategy fail, or was it not executed as tested? |
How Broker Execution Affects Strategy Results
Historical tests rely on assumptions. Live spreads, slippage, swap, liquidity, order handling, and fill quality can differ from those assumptions and change the outcome.
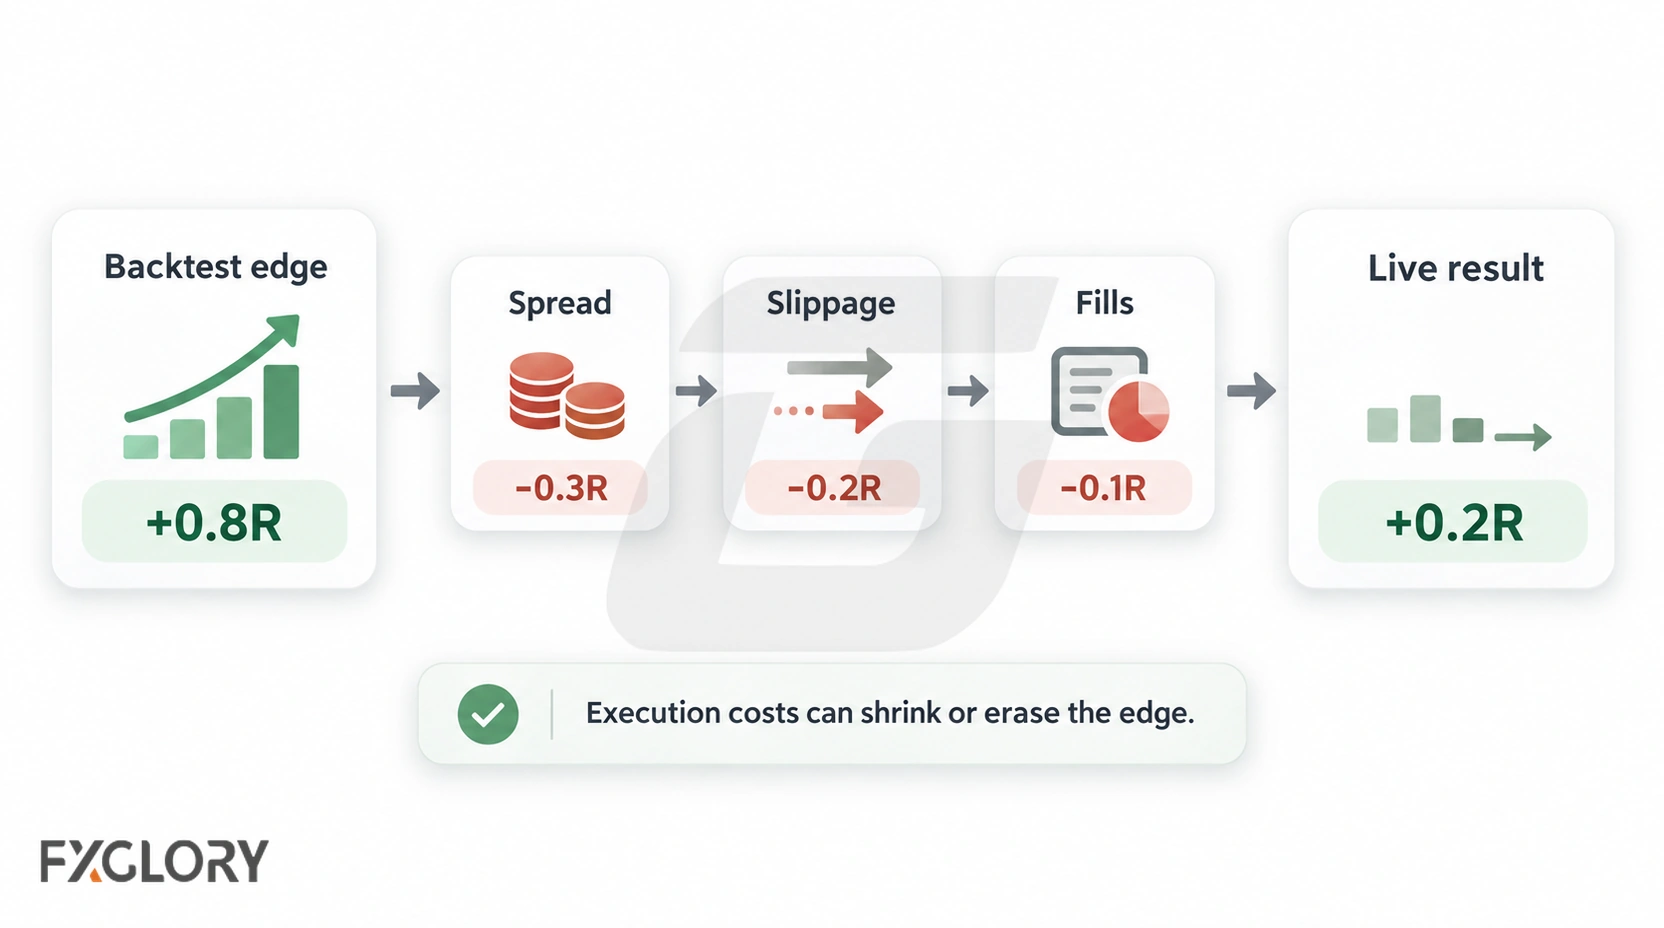
Before live trading, compare current spread conditions, leverage terms, and margin requirements with the assumptions used in testing.
Backtesting a Strategy for Consistency
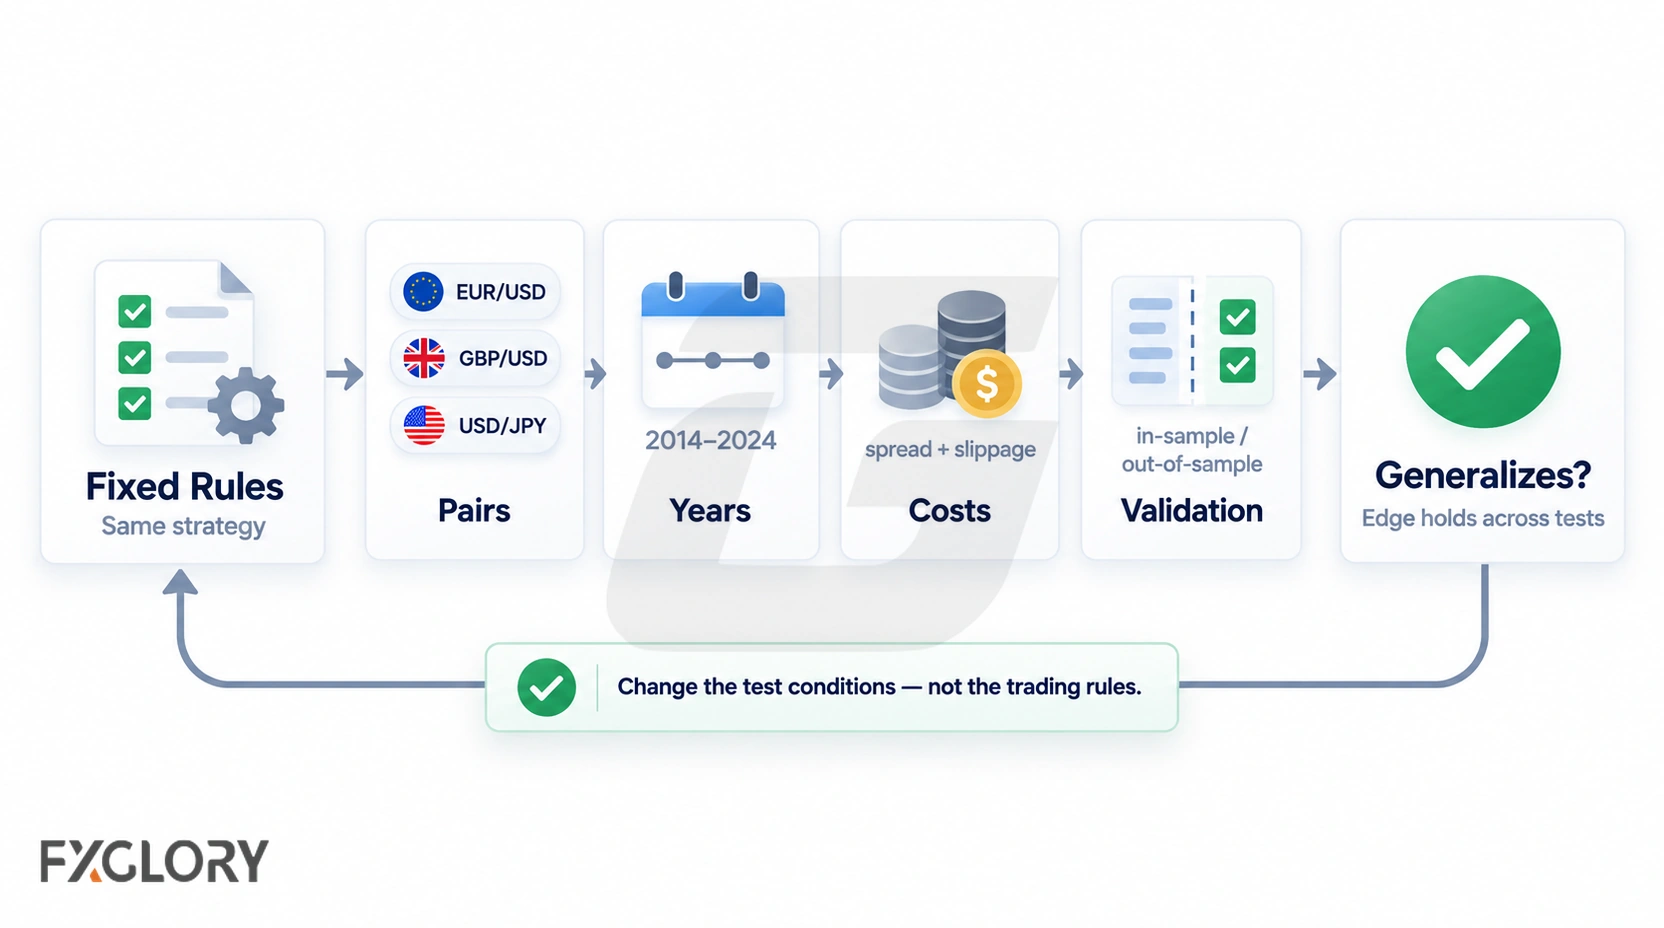
This educational study compares three daily rule models across six currency pairs using historical public-market data from 2014-01-01 through 2024-12-31. The purpose is to show how expectancy, pair variation, costs, trade frequency, and drawdown can differ across rule models. It is not a recommendation to trade any of them.
Rule Models Tested
| Strategy | Entry Rule | Invalidation | Target | Sensitivity Tested |
|---|---|---|---|---|
| Strategy A — Trend + Pullback | Daily close above/below EMA(trend). Pullback to 20 EMA, then close crosses back across 20 EMA in trend direction. Or retest of broken structure. | 5-bar swing beyond pullback or failed breakout structure. | 2R or exit on trend break. Max hold 60 bars. | EMA trend: 40, 50, 60. Each with 3 spreads × 3 slippages = 27 runs per pair. |
| Strategy B — 20-Day Breakout | Daily close above highest high of prior 20 bars (long). Daily close below lowest low of prior 20 bars (short). | Daily close back inside the 20-day range. | 2R or exit on range re-entry. Max hold 60 bars. | 3 spreads × 3 slippages = 9 runs per pair. |
| Strategy C — S/R Mean Reversion | Price touches prior daily swing level with rejection candle (close above open for longs at support, close below open for shorts at resistance; wick ≥ 1.5× body). | Daily close beyond the level by 0.3× 14-period ATR. | 1.5R. Max hold 60 bars. | 3 spreads × 3 slippages = 9 runs per pair. |
Cost and Validation Settings
| Setting | Values Tested | Why It Matters |
|---|---|---|
| Pairs | EURUSD, GBPUSD, USDJPY, AUDUSD, USDCAD, USDCHF | Cross-pair measurement reveals whether results are pair-specific. |
| Date range | 2014-01-01 to 2024-12-31 (daily OHLC) | The sample covers multiple market conditions across the historical period. |
| Spread assumptions | 0.5, 1.5, and 3.0 pips per round trip | Tests how transaction-cost assumptions affect results. |
| Slippage assumptions | 0.1, 0.5, and 1.0 pips per side | Tests sensitivity to execution-price differences. |
| Swap or rollover | Not included — reviewed separately | Holding costs can matter, especially for longer-duration positions. |
How to Read the Sample Size
The study reports both sensitivity-run observations and approximate unique signals. Sensitivity runs repeat the same underlying signals under different cost or parameter assumptions, so they should not be treated as independent trades.
Strategy B generated about 267 unique signals in total, or roughly 44 per pair. Its pair-level estimates should therefore be read with more uncertainty than Strategy A's larger unique-signal sample. The article does not treat 100 trades, 200 trades, or any other fixed count as a universal statistical-significance threshold.
Educational Backtest Results
The following values are preserved from the supplied structured research. They are historical hypothetical results from yfinance public research data, not live broker performance.
Combined Metrics — All Pairs, All Sensitivity Runs
| Metric | Strategy A Trend + Pullback | Strategy B 20-Day Breakout | Strategy C S/R Mean Reversion |
|---|---|---|---|
| Observations (all sensitivity runs) | 21,546 | 2,403 | 10,630 |
| Approx. unique signals | ~800 | ~267 | ~1,181 |
| Win rate | 27.07% | 42.16% | 26.40% |
| Average win | +1.79R | +1.00R | +1.48R |
| Average loss | -0.68R | -0.77R | -1.00R |
| Expectancy | -0.013R | -0.027R | -0.345R |
| Profit factor | 0.97 | 0.94 | 0.53 |
| Max drawdown (aggregate sensitivity result) | -808.28R | -110.60R | -3,668.15R |
| Worst losing streak | 18 trades | 11 trades | 25 trades |
| Avg holding period | 7.31 days | 44.72 days | 7.40 days |
Pair-Level Comparison
| Pair | Strategy A | Strategy B | Strategy C | |||
|---|---|---|---|---|---|---|
| Expectancy | Profit Factor | Expectancy | Profit Factor | Expectancy | Profit Factor | |
| EURUSD | -0.017R | 0.97 | -0.069R | 0.86 | -0.376R | 0.50 |
| GBPUSD | +0.166R | 1.35 | -0.177R | 0.66 | -0.345R | 0.53 |
| USDJPY | -0.029R | 0.94 | +0.250R | 1.85 | -0.377R | 0.50 |
| AUDUSD | -0.059R | 0.89 | -0.215R | 0.59 | -0.343R | 0.53 |
| USDCAD | -0.072R | 0.87 | +0.145R | 1.40 | -0.364R | 0.52 |
| USDCHF | -0.063R | 0.87 | -0.082R | 0.82 | -0.277R | 0.60 |
What the historical results show:
- Win rate alone was not enough. Strategy B had the highest combined win rate, yet its combined expectancy remained negative because average wins and losses produced an unfavorable overall result.
- Pair-level results varied materially. Strategy B produced positive expectancy on USDJPY and USDCAD but negative expectancy on the other four tested pairs. The exact pair-level values are shown in the table above.
- Strategy C was negative across all six tested pairs. Under the tested rules and cost assumptions, its combined expectancy was -0.345R and profit factor 0.53. This describes this specific rule model and historical sample, not mean-reversion strategies as a category.
- Sample uncertainty differs by model. Strategy B's smaller unique-signal count means its pair-level statistics should be interpreted with wider uncertainty than models with more unique signals.